On-Prem AI vs Cloud AI for Regulated Industries in 2026
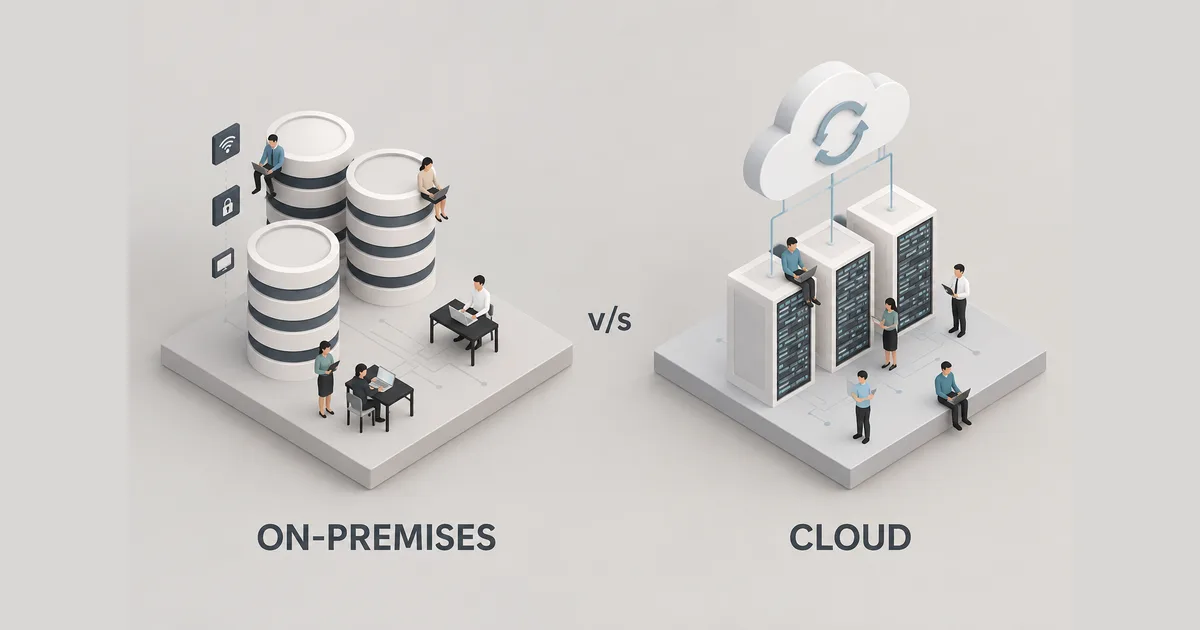
You know the pattern by now. The cloud quote arrives with impressive unit pricing and a three-day onboarding promise. Then compliance review starts. Where does the data actually live? Who else can touch it? What does the audit trail look like? Which jurisdiction does the provider's contract put it under? Each answer reshapes the price, and the gap between the first quote and the real number keeps growing.
This guide breaks down the four deployment modes that matter in 2026. Public cloud, private cloud, on-premise, and air-gapped. It compares them across the eight dimensions that decide the outcome in a regulated industry, explains when each mode fits, and ends with the break-even math your finance team will ask for. No vendor pitches, no competitor comparisons. Just the decision logic, stated plainly.
On-prem AI vs cloud AI at a glance
The table sets up the whole comparison. Read it top to bottom. The rows that usually decide the outcome for a regulated buyer are data residency, compliance surface, and vendor exposure.
| Dimension | Public cloud AI | Private cloud | On-prem | Air-gapped |
|---|---|---|---|---|
| Data residency | Inside a provider region you select. You cannot exclude provider-side access. | Inside a provider-operated environment, logically or physically isolated for your tenant. | Inside your own facility or a facility you contract for. | Never leaves your network boundary. |
| Compliance surface | Provider certifications plus your configuration choices. | Provider certifications plus your tenant configuration and your contracts. | You own the full control stack: physical, network, logical. | Everything on-prem owns, plus proof of isolation from external networks. |
| Cost shape | Per-use. Scales with every query and every token. | Committed spend. Steady platform fee plus usage. | Capital up front, then a low marginal cost per GPU-hour at sustained utilization. | On-prem cost plus the cost of maintaining a true network isolation. |
| Latency | Network hops to the region add latency. Fine for batch, less so for tight loops. | On provider network, usually close to your systems. | Local to your network. The lowest option. | Local to your network. Same profile as on-prem. |
| Ops burden | Lowest. The provider operates the infrastructure. You operate the model layer. | Low to medium. The provider runs the platform, your team runs the AI stack. | High. You run hardware, networking, power, cooling, and patching. | High. Everything on-prem handles, plus controlled transfer processes for models and patches. |
| Model updates | Instant via API. You inherit the provider's release pace. | Fast, through the provider's model catalog or your transfer process. | Manual or scripted. You decide when and how a new model lands. | Through a secure, one-way transfer channel. Slower, and fully auditable. |
| Vendor exposure | Highest. Data, model catalog, and platform all sit behind one provider. | Medium. One provider for the environment, but you keep the model layer portable. | Low. You own the infrastructure; models and tooling stay replaceable. | Lowest. No external dependency in the steady state. |
| Who operates it | The provider, end to end. | The provider plus your platform team. | Your own infrastructure and AI teams. | Your own staff, on site, with no external escalation path. |
1. Public cloud AI
Public cloud is the fast default. You provision GPU capacity or call a model API, and you have a running system the same week. It fits workloads where the data is not highly sensitive, where demand spikes are real, and where time-to-value matters more than control. For a regulated industry, that scope is often narrower than the organization expects.
The cost shape is pure consumption. You pay per GPU-hour or per token, so the bill tracks usage one-for-one. When utilization is low or the workload is experimental, that is a feature, not a defect. When usage is steady and high, the bill never stops climbing, and there is no cap below the negotiated enterprise rate.
The compliance posture rests on the provider. You inherit its certifications, its region menu, and its access model. Your own configuration still decides a lot of the outcome, which is why the same platform can pass one audit and fail another depending on how it was set up. The provider operates the infrastructure, so your team operates the model layer on top.
2. Private cloud
Private cloud gives you a provider-operated environment that is isolated for your tenant. The data stays in a defined region or facility, and the isolation can be logical or physical depending on the offering. It fits organizations that want provider-grade operations without giving up data separation, and it is a common middle step before a full on-prem build.
The cost shape is committed. You sign for a platform fee and a capacity block, which keeps the monthly number flat and predictable. The trade is flexibility: you are buying a fixed envelope, and growth beyond it is a contract conversation, not a slider.
The compliance posture is stronger than public cloud because the data is separated, and the contract usually names the facility and the region. The provider still operates the hardware, and your data still sits on provider-owned infrastructure, which some regimes treat as a real dependency rather than a neutral fact.
Who operates it: the provider runs the platform, and your team runs the AI stack on top. The ops burden is the lowest that keeps your data separated, which is why it is the default middle ground.
3. On-premise
On-premise is the control maximum. The hardware is in a facility you own or contract for, the network is yours, and the access model is yours. It fits workloads where the data must stay inside a defined boundary, where audit requires physical-level answers, and where usage is steady enough to justify the capital. For many regulated industries, that is the majority of production work.
The cost shape flips the cloud model. You take a capital line item for the hardware. An 8-GPU node of current-generation accelerators lands around $300,000 to $400,000. Fully loaded, that node works out to roughly $3.50 per GPU-hour at full utilization. The marginal cost of the next query is close to zero. The catch is that the capital is spent whether or not the node is busy, so utilization becomes the whole game.
The compliance posture is as complete as the team behind it. You own the physical security, the network policy, the logical controls, and the logs. Nothing is delegated. That is the strength, and it is also the reason the ops burden is the highest of the four modes: you run the power, the cooling, the patching, and the on-call.
The deeper cost and workload analysis, including the five hidden line items that show up after the hardware, is covered in Five Hidden Costs Sabotaging Your AI ROI. The cross-cutting strategy of mixing cloud, on-prem, and hybrid, which is where most regulated landings actually settle, is laid out in Cloud vs On-Prem vs Hybrid.
4. Air-gapped
Air-gapped is on-premise plus one more hard requirement. The network has no path to the outside world. No cloud API, no telemetry, no external update channel. It fits the smallest class of workloads: defense and intelligence programs, certain critical-infrastructure control systems, and some research environments where the isolation itself is the requirement.
The cost shape is on-prem cost plus the isolation. You pay for the hardware the same way, and you add the engineering of a clean transfer process for models, patches, and data. The operational cost is real because every change has to move through a controlled channel with verification, and the margin for automation is narrower.
The compliance posture is the strongest of the four, and the proof burden matches it. You have to demonstrate the isolation, not just assert it. The network boundary, the transfer channel, and the audit log all have to stand up to inspection. That is exactly what the Sovereign AI Architecture post maps out, mode by mode.
The hybrid answer
Most regulated buyers in 2026 do not pick one mode. They run several, and the routing rule is sensitivity. The public cloud takes workloads where the data is not sensitive and the requirement is speed. On-prem takes the confidential workloads that must stay inside the boundary. Air-gapped takes the restricted class where isolation is the rule. A private cloud sometimes fills the middle, holding the workloads that need separation but not full facility control.
The routing has to be enforced at the orchestration layer, not by convention. If the same workflow can reach a model in the cloud or a model on-prem depending on the input, the compliance posture is only as strong as the routing rule, and the routing rule has to be testable. That is the practical reason a single orchestration plane across the modes matters more than any single deployment decision.
The budget consequence is that you price each tier on its own terms. Cloud is priced per use. On-prem is priced per node and per utilization. Air-gapped is priced per node plus the transfer process. The total is lower and more defensible than forcing every workload into the most expensive mode that satisfies the strictest rule.
When cloud is actually fine
The honest counter-case first. If the data already lives in a cloud region, if the workload does not touch the most sensitive classes, and if your auditor accepts the provider's certifications plus your configuration, then public cloud is the right answer, and building on-prem to avoid it is a cost center, not a control.
The same is true for experimentation and early development. The value of cloud in the prototype phase is speed and near-zero fixed cost. You learn what the workload needs before you commit capital to a node that may end up half empty. Several of the organizations that ended up with a hybrid stack started exactly here, on cloud, and moved only the production confidential tier on-prem once usage was proven.
The test is simple. Ask whether the workload has a compliance reason to be off cloud, or a cost reason to be on it. If neither, the mode should follow the data and the usage, not the default.
What this means for the budget
The break-even is the number finance will ask for. At roughly $3.50 per GPU-hour for a fully loaded on-prem node, and $2.50 to $7.00 per GPU-hour in the cloud depending on the accelerator and the contract, on-prem stops losing to cloud once your utilization is sustained above the midpoint. Below about 50% sustained utilization, cloud is cheaper, because you are paying for capacity you do not use. Above it, the flat on-prem cost wins, because every extra query is nearly free.
Two things move that line. The first is the price of the node. Accelerator pricing falls with each generation, which pushes the break-even utilization down and makes on-prem rational at lower volumes than it was two years ago. The second is the shape of the demand. A workload that runs 24/7, like a production inference service, sits on the right side of the line by default. A workload that runs in bursts during business hours sits on the left, and the capital is wasted.
The strategic point is that the break-even decides the on-prem tier, not the whole strategy. The workloads with a compliance reason to stay inside your boundary land on-prem or air-gapped regardless of utilization, because the alternative is not available. The remaining workloads, the ones with no residency or isolation requirement, should follow the cloud cost curve. Price the two tiers separately, and the budget becomes a routing decision instead of a build-versus-buy argument.
Last verified: 2026-09-10
Why Executives in Regulated Industries Choose Shakudo to power their AI on infrastructure they control
-
Data residency by architecture
Shakudo runs in your data center, your private cloud, or an air-gapped network, so data boundaries are set by your infrastructure rather than by a provider's region menu.
-
Audit-ready operations
Every model, data source, and workflow step is versioned and logged, giving auditors a complete and queryable record of what ran and where it ran.
-
Vendor-agnostic models
Open and commercial models are managed as tracked artifacts. Your stack is not tied to a single provider's model catalog or API.
-
Cost predictability at scale
On your own infrastructure, compute cost stops scaling with every query. The platform works on any hardware you deploy, so utilization drives the unit cost down.

Frequently asked questions
Is on-prem always cheaper than cloud AI?
No. On-prem costs are fixed, so they win at sustained, high utilization and lose when usage is light or spiky. Cloud is usually cheaper below a meaningful utilization threshold, which is why most regulated buyers run a mix.
Can you still use open models on-prem?
Yes. Open models are common on-prem because you control the license and the hardware. They also make model updates and transfer simpler, since no provider API sits between you and the weights.
What about model updates without internet?
Air-gapped updates move model artifacts through a controlled, one-way transfer channel with hash verification. The model is still a tracked artifact with a documented version, so you can roll back or audit each change.
When does regulated mean air-gapped?
When the requirement is physical or network isolation, not just logical separation. This is typical for certain defense, intelligence, and critical-infrastructure programs, and for some classified research environments.